Verifying Code Without Reading It

It is a familiar observation by now that most code review happens without anyone reading the code (the case is made in You Already Review Code Without Reading It). That observation leaves a question hanging. If no human reads the diff, how do you still get correctness, maintainability, extensibility, and the rest of the things review was supposed to deliver?

The short answer is that you stop trying to read, and start trying to verify. Reading is one tool doing many jobs poorly. Verification is many tools, each doing one job well. Done right, the unread change is checked more thoroughly than the read one ever was.

Decompose What “Reading” Was Checking
#

When a reviewer reads code, they are not doing one thing. They are running a dozen checks in their head at once, and doing each of them inconsistently. Make those checks explicit, and a different picture appears.

Correctness: does the code do what the task actually asked for? Tested: are the behaviors that matter covered by tests that would fail if the code were wrong? Maintainable: is the complexity bounded, the duplication low, the naming consistent, the dead code absent? Extensible: can the next change plug in without a rewrite, or has this change welded two things together that should stay apart? Secure: does it cross a trust boundary, leak a secret, or open an injection path? Reversible: if this is wrong, can we undo it in minutes, or does it mutate data we cannot get back?

A tired reviewer scans for all of these at once and catches each of them sometimes. The move is to give each property its own check, run on every change, without getting tired.

Match Each Property To Its Best Checker
#

Every property above has a checker that is cheaper and more reliable than a human reading a diff.

Correctness is checked by tests, and by an LLM judge that compares the diff against the acceptance criteria from the issue and asks: is there a case where the criteria hold but this code fails? Tested is checked by coverage gates and by mutation testing, which mutates the code and fails the build if the tests still pass, because that means the tests were not testing anything. Maintainable is checked by complexity limits, duplication detectors, dead-code scans, and linters, all deterministic, all running every push. Extensible is checked by dependency-direction rules, boundary tests, and an LLM critic that asks where the next feature would plug in and whether this change has made that harder. Secure is checked by static analysis, secret scanning, and an adversarial LLM pass that tries to find the input the author did not think of. Reversible is checked by a blast-radius classifier: did this touch the schema, the public API, an external commitment, or a trust boundary?

None of these requires a human to read the code. Together they cover everything a reader was supposed to cover, and they cover it on every change, not on the changes a reviewer happened to be alert for.

The LLM As Critic, Not Reader
#

The LLM’s role in this system is not to read the code for you. A summary of the diff is theater with a different font. The LLM’s role is to act as a critic against a single, stated property.

Give it the diff, the specification, and one question. Does this change introduce a coupling that violates the intended dependency direction? Is there an input that bypasses the authorization check the spec requires? Does this function do something the acceptance criteria never asked for? One question per critic, phrased so the answer is either a concrete failing case or a pass.

This is verification, not reading. It is adversarial by construction: the critic is rewarded for finding a problem, not for approving. And because each critic has one job, you can run many in parallel, each a different prompt, each looking for a different class of failure. A human reader tries to notice everything and notices some of it. A battery of critics tries to notice one thing each and notices it every time.

Verification Is Not Validation
#

There is a distinction worth holding onto, because the system fails if you blur it.

Verification asks: did we build the thing right, does the code meet its specification? Validation asks: did we build the right thing, does the specification solve the real problem?

Reading a diff does verification badly and validation not at all. No amount of staring at code tells you whether the feature should exist. That judgment has to live somewhere, and the productive place for it is upstream, in the specification, and downstream, in production.

So split the work. Put verification in the automated gates, where machines check the code against a precise spec on every change. Put validation upstream, where humans decide which problems are worth solving and write the acceptance criteria that encode that judgment. Put a third layer of validation downstream, in canaries, monitoring, and fast rollback, where production behavior is the ground truth no diff review can match.

The human does not read the code. The human writes what the code must satisfy, and then watches what the code does in production.

The Circularity Trap
#

There is one failure mode that will quietly ruin this system if you let it go unchecked. Do not let the same model, or the same prompt, both write the code and approve it.

When the author and the verifier share a mind, the verifier inherits the author’s blind spots. A model that wrote a subtle bug will, asked to review its own work, tend to confirm that the work is fine. This is not malice; it is the same statistical process producing both answers.

The defense is structural. Use a different model for verification than for generation, or at minimum a different agent with a different prompt and different access to the specification. Write the verification criteria before the code exists, so they describe the intended behavior rather than rationalizing whatever was built. And run an adversarial pass whose only goal is to break the change, with no incentive to approve.

Separation of concerns is not a nicety here; it is the whole reason the system can be trusted.

What The Human Does Instead
#

If the human is not reading diffs, what are they doing?

They write the specification and its acceptance criteria, because that is where validation lives and where the LLM’s verification is anchored. They review the rules the gates enforce, not the code the gates pass, because a bad rule approved once produces bad approvals forever, while a bad line of code is caught by a good rule. They respond to gate failures, which is where their judgment adds value, instead of spending it on changes that passed cleanly. And they read code only on the small, flagged minority of changes that carry real blast radius, where a deliberate read is still the best tool we have.

The new division of labor is more work at the top of the pipeline and less at the bottom, which is the right inversion. You are trading a low-leverage activity that scaled poorly (reading every diff) for a high-leverage one that compounds (writing the rules and specs that check every diff).

How You Know It Is Working
#

The objection that will come is simple: how do you know the unread code is good enough?

You do not answer it by pointing at how much code you read. You answer it by measuring the outcomes reading was supposed to produce.

Track defect escape rate, the bugs that reach production per change. Track rollback rate, how often a merged change has to be undone. Track time-to-detect, how quickly a regression surfaces after it lands. Track change failure rate, the fraction of deployments that cause an outage.

Run the new system on a slice of changes and compare these numbers to your old, human-read pipeline. If the gates have a lower defect escape rate and a faster cycle time than your reviewers did, the unread code is provably better than the read code was. If they do not, you have a concrete gap to close, by tightening a rule or adding a critic, not by urging reviewers to read harder.

The standard is not “a human looked at it.” The standard is “the code behaves well in production, measurably, on every change.” A human looking at it was always a proxy for that standard, and a weak one. Replace the proxy with the thing it was standing in for.

See also
#


You Already Review Code Without Reading It

Most code review does not involve reading code. The decision to approve is made before the diff opens. We keep the ritual, and quietly drop the part that is supposed to justify it.

The gap between the ritual and the reading has a mirror on the other side of the pull request. An LLM cannot vouch for its own output, because accepting a solution as done needs information the model does not have (The Acceptance Gap). The reviewer has the same problem in reverse: vouching for code that was never read.

What I Mean By Reading
#

There is a difference between opening a pull request and reading one. Reading means reconstructing what the code does, tracing each branch, checking every assumption against the rest of the system, and forming an independent opinion about whether it is correct. That takes time, and sustained focus, and the kind of attention that does not survive a fifteen-item review queue.

Opening is something else. You open the PR, your eye catches the file list, the green check from CI, the test count, the description the author wrote, and within a few seconds a feeling forms: this is fine, or this is not. The code itself sits downstream of all of that. Most of the time, you never reach it.

This is not a failure of discipline. It is how the tool presents work to you, and how a busy engineer responds to that presentation. The diff is the last tab you look at, and often the one you look at least.

The Signals That Actually Decide Approval
#

If you watch what an approver actually responds to, the code is rarely the first thing.

CI passed. That carries more weight than any line you might have read. The tests are green, the build is green, the linter is quiet, and that cluster of signals has already done the safety work before you arrived.

Then the author. A pull request from someone you trust gets a lighter read than one from a new hire. You will deny this in a meeting and do it anyway in practice. Trust is a real signal, and a useful one, but it is not “reading the code”.

Then the size of the change. A two-line diff to a README merges in seconds. A four-hundred-line refactor to the auth module stalls. You are reacting to blast radius, not to semantics, and you are right to, but again, that is not reading.

Then the description and the linked issue. These tell you what the author intended. For a lot of pull requests, the intent is all you ever verify, because the code is too long to verify against it in the time you have.

The code is the alibi. The signals are the verdict.

Why We Pretend To Read
#

If the code is not really what we are checking, why the ceremony around it?

Because reading code is the thing code review is supposed to be for. Admit that you are not doing it, and you admit that the central activity of the gate is not happening. That is an uncomfortable admission, so it does not get made. Instead we keep the form, the comments, the approving review, and let the substance slide.

There is also a blame function. When something breaks, we want to point at a name on the pull request and say “they signed off”. The signature has to mean “I read this and vouched for it”, or it cannot carry that blame. So we maintain the fiction that the signature means what it says, even though everyone, on both sides, knows it often does not.

This is accountability theater: the approve click certifies that a person was present, but rarely certifies that the code was read. The signature allocates blame after the fact. It does not prevent harm before it.

The Self-Test
#

Here is a test you can run on yourself. Approve your next five pull requests the way you normally would. The next day, try to recall a single line of code from each one.

If you cannot, be precise about what that means. It means you approved metadata. You were responding to CI, to the author, to the description, to the size of the diff, to your sense of the person. Those are signals, and some of them are good signals. But none of them are “I read this code and understood it”.

Run the same test on your team. Ask a recent approver to explain, from memory, one function that changed in the pull request they approved. The silence you get back is the most truthful data you will collect about how code review actually works in your organization.

I am not mocking reviewers here. I have failed this test more often than I have passed it. The point is that the gap between what review is supposed to be and what it is, is large, and we never measure it because measuring it would force a conclusion we have already decided not to reach.

Two Real Paths
#

Once you accept that most review does not involve reading, you have two defensible directions, and only two.

The first is to actually read the code, on the changes that warrant it. Not every change. The ones with real blast radius: irreversible changes, trust-boundary changes, changes to the gating system itself. On those, slow down, read deliberately, trace the logic, and form an independent opinion. This is high-leverage work, and it is rare, and it deserves the time it takes.

The second is to drop the pretense, and let the changes you were never going to read merge on the strength of the signals you were actually using. Green CI, a passing test suite, a trusted author, a small reversible diff. These already decided the outcome. Let them decide it without a human in the middle adding latency and taking credit.

What is not defensible is the current default. The default is the second path, with the theater of the first layered on top. You approve without reading, but you still require a human to approve without reading, and you call the combination a quality gate.

When The Code Was Written By A Machine
#

This was already true when humans wrote the code. It is sharper now that machines do.

When an LLM generates the diff, reading it line by line is even less useful, for reasons explored in Rethinking Code Review in the Age of LLMs. The reviewer becomes the only mind in the loop, reconstructing intent from output, and that reconstruction is harder and slower than reviewing a human who can at least be asked what they meant.

So the metadata review does not get more rigorous by being relabeled a code review. It gets more exhausting, and less effective, for the same rubber stamp at the end.

If you were not reading human-written code, you are not going to start reading machine-written code. You are going to keep approving signals, with a worse feeling about it. The productive move is to put the effort where it was always worth more: upstream, in the specification, the tests, and the gates.

What to Do Next
#

You do not need permission to start. Pick the low-blast-radius path and let it merge on green. Then be plain with your team about what the rest of the approvals were already doing.

When a change is large, irreversible, or crosses a trust boundary, read it for real. Budget the time. Treat it as the exception it is, not as the default dressed up as diligence.

And measure the gap. Ask your approvers what they remember from the pull requests they approved. The number will embarrass you, and that embarrassment is the beginning of a review process that is actually worth its cost.

See also
#


Issues Are Free Now: Send the Implementation, Not the Idea

For most of software’s history, filing an issue took real work. You had to reproduce the bug, narrow it down, write a clear description, and decide whether the request was worth the maintainer’s time. That filter is gone. An AI agent can read a README, a changelog, or spend ten minutes with the tool, and produce a polished, well-formatted issue in seconds, and it can do it a hundred times before lunch. The cost of creating an issue fell to almost nothing, the cost of clearing one did not, and every issue tracker on the internet is now overflowing.

If you are the one filing those issues, the result is hard to hear but clear. The issue you just opened is no longer a contribution in any real sense. It is a request for someone else’s work, and it is sitting in a queue next to nine hundred other requests for someone else’s work, most of them produced just as cheaply as yours. The only thing that still moves the needle is the implementation attached to the request, because the implementation is the one input whose cost has not fallen.

The Issue Tracker Was Always a Wish List
#

It is worth being clear about what an issue tracker actually was, even before AI. A well-written bug report was a real gift, because it gave the maintainer a reproduction and a starting point. A feature request was almost always a wish. Someone else should do this. Someone else should want this. Someone else should spend their Saturday on the thing I would like to have.

Maintainers cleared the gifts and let the wishes pile up, and that was fine, because the wishes cost the filer enough effort to write that only the motivated ones made it through. The friction was the filter. The issue tracker was tolerable only because filing an issue was mildly annoying, and the mildly annoyed filer self-selected for “I actually care.”

Remove the friction and the wish list becomes the whole tracker. That is where we are.

The Cost Imbalance Is the Whole Problem
#

The math that kills the tracker is simple. It costs a filer roughly zero seconds and zero cents to open an issue with an AI agent. It costs a maintainer anywhere from five minutes to an afternoon to triage it: read the request, check whether it duplicates something, decide whether the project wants it, find the relevant code, and either close it, schedule it, or do it. One side of that exchange is free; the other side is unpaid, and the unpaid side is the one you are asking to work.

Multiply that imbalance by a few hundred issues a week and you get the current state of every popular open source repository on the planet. The triage queue grows faster than any single human can read it, the maintainer starts ignoring the tab, the contributor waits six months for a reply, and the project slowly gains a reputation for being unresponsive. Nobody is at fault. The system is just balanced so that the cheap side produces faster than the expensive side can consume, and the buffer between them is a person.

This is the same dynamic I described for pull requests in The Pull Request Queue Outgrew You: the cost to create a change fell below the cost to review it, and the maintainer became the bottleneck in their own queue. What is true for code changes is now true for ideas, and ideas are even cheaper to produce.

An Implementation Rewrites the Ask
#

Here is the move that fixes the imbalance, and it is the only move that fixes it. Stop sending the description. Send the code.

A pull request with a working implementation changes the maintainer’s job from “do this work” to “evaluate this work,” and those are not the same task. Doing the work is open-ended, expensive, and unpaid. Evaluating the work is limited, fast, and something a maintainer can actually fit into a Saturday morning. The difference between “you should add a dark mode” and “here is a dark mode, here are the tests, here is the screenshot, merge or reject” is the difference between a request for a favor and an offer to work together. The implementation is what converts your issue from a cost imposed on the maintainer into an option extended to them.

This is also why the maintainer is so much more likely to act on a pull request than on an issue. A PR gives them a simple choice they can make in minutes. An issue gives them an open-ended commitment that will eat an afternoon if they engage with it at all. If you wonder why your feature request has sat untouched for two years while a stranger’s twenty-line PR landed in a week, that is the entire explanation. The PR was cheap to say yes to. Your issue was expensive to say yes to, and expensive to say no to, so it got neither, which is what happens to expensive things in a full queue.

The Cost of Implementing Fell Too
#

The obvious pushback is that not everyone can write the implementation, and that used to be true. It is not true anymore.

The same AI agent that filed the issue can write the pull request. You describe what you want, the agent reads the codebase, produces a diff, writes the tests, and opens the PR. The skill floor for “I can send a working implementation” dropped from senior engineer to motivated user with a coding agent and an afternoon. The reason to keep sending descriptions instead of implementations is no longer that you cannot produce the implementation. It is that you have not updated your habits to match the new cost structure.

This is the same shift The Shifting Bottleneck keeps arriving at. Producing code is no longer the constraint. Deciding what to produce, and accepting what got produced, is the constraint. In an issue tracker, that means the scarce resource is no longer “someone willing to file the issue” or even “someone willing to write the code.” The scarce resource is the maintainer’s attention, and the only way to earn a slice of it is to bring the work to a state where saying yes costs them almost nothing.

But I Am Not Sure My Implementation Is Good
#

This is the second pushback, and it is more serious than the first. You worry that sending an AI-generated PR is dumping low-quality work on an already overloaded maintainer, and that is a real risk. The answer is not to hold back the PR. The answer is to do the work that makes the PR cheap to evaluate.

Run the tests. Write a new one for the behavior you added. Reproduce the bug you claim to fix, and show the test going red before your patch and green after. Keep the change small and focused on one thing. Link the issue you are closing. Write a PR description that lets the maintainer evaluate the change in thirty seconds. Every one of these is an attempt to lower the cost of saying yes, and lowering the cost of saying yes is the entire game.

A small, tested, well-described PR is a gift. A large, untested, AI-generated diff with a one-line description is just a different kind of issue, and it will be treated like one. The discipline is not “send code instead of an issue.” The discipline is “send code that is cheaper to merge than to discuss, and if you cannot produce that, the issue tracker will not save you either.”

What the Maintainer Actually Wants
#

It helps to look at the exchange from the maintainer’s chair for a moment, because the request they are implicitly making is not unreasonable. They want to spend their scarce attention on decisions only they can make: the architecture, the direction, the boundary between what the project is and is not. They do not want to spend it turning a feature description into code, because that is the part the LLM can do now. The highest-value contribution you can make is one that arrives with every reversible decision already made and every test already green, so that the maintainer’s job is reduced to a judgment call they were going to have to make anyway.

This is the open source version of the argument in Rethinking Code Review in the Age of LLMs. When the implementation is cheap to produce, the value concentrates upstream, at the point where someone decides what the implementation should be. A good contributor in this era is not someone who writes clean code. A good contributor is someone who arrives with a concrete proposal, already implemented, already tested, already de-risked, leaving the maintainer nothing to do but approve, redirect, or reject.

What About Bugs You Cannot Reproduce
#

There is a real exception, and it should be named so the argument does not go too far. Some issues are genuine bug reports where the value is in the reproduction, not in the fix. A crash that happens on a specific kernel version, a regression that only shows up under load, a data corruption bug that requires a particular sequence of inputs. These are gifts, when written carefully, because the maintainer could not have produced the reproduction themselves.

But notice what makes them gifts. They carry information the maintainer did not have and could not get cheaply. The test for whether your issue is a contribution or noise is exactly this: does it contain information the maintainer could not have produced on their own in fifteen minutes with an AI agent? If yes, file it. If no, the issue is a request for someone else to do work you could have done yourself, and the queue is full of those already.

The same test separates a useful feature request from noise. “Add dark mode” is noise. “Add dark mode, here is the design, here is why it does not conflict with the theming system, here is the PR, here are the screenshots, here are the tests” is a contribution. The information that converts noise into contribution is exactly the information that comes from having tried to build the thing.

What to Do Next
#

If you file issues against projects you depend on, change one habit. Before you open the issue, try to open the PR instead. Point an agent at the codebase, describe the change you want, and let it produce a draft. Spend the time you would have spent polishing the issue description on getting the PR to a state where merging it is the obvious move: tests passing, scope small, description clear. File the issue only if the PR attempt really failed, and when you do, include what you learned from the attempt, because that is the information the maintainer actually needs.

If you maintain a project, change the default you invite. Rewrite your contributing guide to say, plainly, that feature requests without an accompanying PR will be closed, and that bug reports without a reproduction will be closed faster. Be clear that this is not hostility. It is the only way the queue stays a queue instead of a landfill. Make the pull request template the front door, and the issue template the side door for the narrow set of things only an issue can carry. Raising the floor on contributions is, in this era, an act of respect for the contributors who are willing to meet it, because they are the ones whose work will otherwise be buried under the noise.

And for everyone, learn the new cost structure. Ideas are free. Descriptions are free. Issues are free. Implementations are the only currency left that buys maintainer attention, and the reason is not that maintainers are picky. It is that implementations are the one input whose cost has not fallen to zero, which makes them the one input that still signals you meant it. If you want a maintainer to take your request seriously, prove it the only way that still costs you something: by sending the code.

See also
#

  • The Pull Request Queue Outgrew You - the companion argument from the maintainer’s side: the cost to create a change fell below the cost to review it, and triage has to replace review
  • The Shifting Bottleneck - the upstream pattern: producing code is no longer the constraint, deciding and accepting are, which relocates where contribution lives
  • Rethinking Code Review in the Age of LLMs - why value concentrates upstream at the decision point when implementation becomes cheap
  • The Acceptance Gap - the maintainer’s remaining job is acceptance, and an implementation is what lets them do that job in minutes instead of afternoons
  • Feature Parity Is Not a Moat - the parallel collapse of copy-time, which made features cheap to clone the same way AI made issues cheap to file

Who Resolves the Merge Conflict? Why the Bot and the Author Are Not Interchangeable

A pull request falls behind main and conflicts. Who resolves the conflict, the bot or the author? The answer depends on whether the conflict is mechanical or semantic, and treating the two as the same job is what makes every flat policy, “the bot rebases everything” or “the author handles it,” wrong.

The clean rebase is settled and out of scope; automate it on every push to main. The live question is the conflict, and the conflict is not one thing. Resolving a conflict means deciding what the code should now say, and that decision is a claim about what the author meant. Someone has to make it, and the interesting question is who can back it with intent they actually hold. The choice depends entirely on whether the conflict has a unique correct answer an oracle can check, or whether its correctness lives only in the author’s head.

Why the Question Got Loud
#

For most of git’s history the conflict question was quiet. A contributor resolved their own conflicts, or the maintainer did, and the round trip was short because the people involved shared a mental model of the code. Two things broke that equilibrium.

The first is auto-merge. Once low-risk changes land on green without a human clicking merge, a PR that cannot merge cleanly becomes the thing that stalls the whole lane. A human can absorb a conflicted PR by glancing and clicking; an automated merge pipeline cannot. Auto-merge makes conflict resolution a prerequisite of the lane, and that turns “who resolves” from a courtesy into a structural question.

The second is the model-authored pull request. When the author is a model, the conflict round trip behaves differently at both ends. The bot never sleeps, so a resolve request adds no latency the way it does for a human. But the bot also has no private knowledge of what the code was meant to do, so its resolution is a guess about intent dressed up as a fix. This is the plausibility problem, and it lands hardest exactly where the conflict is hardest.

So the modern repository has a lane that wants every PR mergeable on green, and a growing share of PRs whose intent lives only in the code a model produced, with no description, linked issue, or spec that states it independently. When the intent is encoded somewhere, a conflict has an oracle to check a resolution against. When it is not, there is nothing to verify the resolution by, and that, not the absence of an author to interrogate, is the actual problem. The old default, the contributor resolves, is too slow for the merge lane, and the bot is too confident to stand in as the oracle, so the live question is not who authored the PR but whether the intent exists outside someone’s head.

The Conflict Has a Gradient
#

Conflicts are not all the same, and the gradient is what lets you route them accurately.

At one end is the mechanical conflict: an import added in both branches, a trailing comma, two functions inserted at adjacent positions, a formatting drift the formatter can settle. Resolve it and there is exactly one answer any reasonable developer would accept, and a test suite that passes before will pass after. At the other end is the semantic conflict: two people changed the same logic for different reasons, and the correct resolution depends on which reason was right. The mechanical conflict has a unique correct answer that a test can falsify; the semantic conflict has no correct answer without the intent that motivated the change.

The mechanical conflict is therefore still logistics, just logistics that needs an oracle. Resolve it, run the suite, and if the suite passes the resolution is, by construction, the one the project already trusted. Here the test acts as the independent oracle the model cannot be, the same role it plays in closing the bug gap when a fix claims to be done. A conflict whose wrongness a test can catch is a conflict the bot may resolve, because the test, not the model, is signing off.

The semantic conflict is a different animal. Nothing external is left to disagree with the model’s plausible stitch, because the definition of “correct” is the intent, and the intent is precisely what the model does not have. A bot that resolves a semantic conflict is making an intent claim it cannot source, and the harder the disagreement, the more likely the claim is a confident fabrication.

Where the Intent Lives
#

The semantic conflict splits once more, and it splits on a cleaner axis than who wrote the PR: whether the intent is encoded anywhere a resolver can read it.

Intent can live in two places. It can be encoded, written down in the PR description, a linked issue, an acceptance criterion, a failing test, anything a human authored to state what the change was supposed to do. Or it can be tacit, held in someone’s head and never written down, surfacing only if you ask. A conflict is safe for the bot to resolve when the intent is encoded and the encoded source covers the disputed region, because then the resolution has an oracle. It is not safe when the intent is tacit, because then nothing external can falsify the bot’s stitch, and the stitch will look right whether or not it is.

Author type matters, but only as a proxy for where the intent lives, and the proxy is worth stating because it inverts the naive assumption.

When the PR is human-authored, the human’s own description is an independent statement of intent. If the description covers the conflict, the bot may resolve against it, and the description, not the model, is the oracle. If the description is thin or silent on the disputed region, the intent is effectively tacit, and the only defensible move is to ask the human who holds it.

When the PR is bot-authored, the trap is that the bot’s description is not an independent oracle. It was written by the same model that wrote the code, or a sibling of it, so checking the resolution against the description is checking the model against its own narration, which provides no real verification. The only trustworthy intent source for a bot-authored PR is something a human wrote upstream: the issue, the spec, the prompt, an acceptance test. When that upstream source exists and covers the conflict, the bot may re-derive against it, and the re-derivation is checkable. When it does not exist, the intent was never encoded by anyone, and the bot’s resolution is a guess about intent no one ever wrote down.

This is the refinement the flat “maintainer picks a default” framing misses. A single repository-wide default is too coarse, because the right default is a function of whether the PR carries an encoded, independent intent source, and that varies PR by PR, not repository by repository. The PR that links a human-authored issue with acceptance criteria is safe for bot resolution regardless of who wrote the code; the PR that arrives as code and a self-description is not safe regardless of who wrote the code.

The Label Is the Right Mechanism, the Default Is the Question
#

Given the split, the mechanism worth reaching for is the one the question already points at: a label on the PR that decides who resolves a conflict. Labels are already how a modern triage layer expresses every other routing decision, and conflict resolution is no different in kind. The label should express the thing that actually varies, which is not “is this PR rebased” but “who is allowed to resolve a semantic conflict on it.”

For a mechanical conflict there is no decision worth encoding: the bot resolves, the test gates, and a conflict: auto-resolved note is enough audit trail. The label earns its keep at the semantic tier. Something like conflict: author-resolves versus conflict: bot-may-resolve, defaulted per repository by the maintainers and overridable per PR, is the right form, and it is the form the question proposes.

The interesting work is in the default, and the sound default routes on intent availability, not on author type. A PR that links a human-authored issue or spec, with acceptance criteria that cover the change, defaults to bot-may-resolve, because the resolution has an oracle. A PR that arrives as code alone, with no independent statement of intent, defaults to author-resolves, because nothing can falsify the bot’s stitch. The maintainer’s real choice is not “auto or manual.” It is “what do we assume about a PR whose intent source we cannot verify.” The conservative answer, treat the PR as unencoded and ask the author, costs a little latency where the bot could have handled it. The permissive answer, resolve and trust the model, costs intent claims that are silently wrong. Between losing a little speed and shipping a confidently wrong merge, the speed is the cheaper loss, so the default for a PR with no verifiable intent source should be author-resolves.

This makes the highest-leverage change a documentation change, not a tooling one. Require, in the pull request template, a linked issue or a short intent statement that covers the change, and ask whether the PR was model-assisted. The linked issue turns an unencoded PR into an encoded one; the model-assisted flag tells you whether the PR’s own description can serve as an oracle or whether you need the upstream source. Both shrink the “no verifiable intent” bucket, and shrinking that bucket is what lets the auto-merge lane actually run.

What to Do Next
#

First, surface the conflict instead of hiding it. Add eps1lon/actions-label-merge-conflict so any PR that falls behind main gets a merge-conflict label the moment it conflicts, and loses it the moment it merges again. Your auto-merge lane can now filter -label:merge-conflict and only act on work that is actually ready. The author gets an automated nudge that a real decision is needed, without you being the one to say it.

Second, classify the conflict before you route it. Mechanical conflicts (imports, formatting, adjacent non-overlapping edits) go to the bot behind the test gate, and the test is the oracle that makes the resolution trustworthy. If the suite fails, the resolution is wrong by definition and the bot escalates rather than ships.

Third, route the semantic conflict by whether an independent intent source exists. If the PR links a human-authored issue or spec that covers the disputed region, let the bot resolve and check the result against that source, with an encoded test that must pass on the resolved tree. If the PR carries no such source, post the conflict as a comment and drop the PR to author-resolves until someone provides the intent or resolves it by hand.

Fourth, choose the conservative default for the case where you cannot tell. When a PR arrives with no linked issue and no intent statement, default to author-resolves, because the cost of a confidently wrong merge is higher than the cost of a round trip, and the round trip at least asks the question the silent resolution skips.

Fifth, make the routing signal cheap to produce. Require a linked issue or a short intent statement in the pull request template, and ask whether the PR was model-assisted. The link is what turns an unencoded PR into an encoded one, and the model-assisted flag is what tells you whether the PR’s own description can count as the oracle.

Do not write a policy that says “the bot resolves everything” or “the author resolves everything.” Both are the original mistake in policy form. Gate the mechanical conflict behind a test, defer the semantic conflict to an independent intent source when one exists, and defer to the author when one does not.

See also
#

  • Triaging Open Source Pull Requests - the upstream layer this refines: labeling merge conflicts and routing by risk is the triage move, and conflict-tier routing is what makes the auto-merge lane inside that layer safe
  • The Merge Gate - the case for gating on the properties of a change rather than on the existence of a PR, which is the same principle applied here to “is this a mechanical conflict or a semantic one”
  • The Acceptance Gap: Why an LLM Solution Is Not a Shipped Solution - why a conflict resolution is a mini-acceptance gap: the mechanical tier wants a check (verification), and the semantic tier wants the author’s reaction (validation)
  • Rethinking Code Review in the Age of LLMs - the plausibility problem in full, the reason a bot resolving a semantic conflict is making a claim about intent it cannot source

Feature Parity Is Not a Moat: Compete on What Does Not Clone

For most of software’s history, shipping a feature bought you a window. A competitor had to understand the need, design the thing, build it, test it, and ship it. That took weeks or months, during which you could compound users, data, and trust. That window has collapsed to days, sometimes hours, and the uncomfortable implication is that the feature was never the moat. The slowness of copying it was. Once the copying is nearly free, every hour spent perfecting a feature is an hour spent on the one layer the market just commoditized, and the advantage has moved somewhere developers were trained to undervalue.

The Moat Was Always Somewhere Else
#

An economic moat is the structural thing that lets a business keep its profits against competitors. The standard list of what counts as one is telling: switching costs, network effects, cost advantages, intangible assets like brand and patents, and efficient scale. A feature is not on that list. A feature is something you build in the hope that a moat forms around it, through usage, data, or habit, before anyone else arrives.

For a long time the list and the feature felt like the same thing, because copying was slow. You shipped the recommendation engine, and by the time a rival reverse-engineered it, your users had generated enough behavior to make yours better. You shipped the dashboard, and by the time it was cloned, your customers had wired it into their weekly review and would not move. The feature was the seed, and the copy-time was the growing season, and the moat was the harvest. The copy-time is gone, which means the growing season is gone, which means a feature shipped with no other plan now arrives at the market with no moat attached.

What Actually Clones, and What Does Not
#

It is worth being clear about the boundary, because the claim is not that everything is copyable.

What clones easily is the surface. The visible feature, the UI flow, the API surface, the integration that calls a public endpoint, the report that joins two tables. A capable engineer with an LLM can reproduce any of these from a screenshot or a description in an afternoon, and a competitor can ship a credible copy in a week. The commoditization of the application layer is real, and it is fast.

What does not clone is everything that had to be true for the feature to be valuable in the first place. The two years of usage data that makes the recommendation correct. The thousand integrations already in your customers’ workflows. The track record of reliability that makes a procurement officer sign. The deep, specific knowledge of a narrow industry that lets you pick the right feature to build next. The competitor can copy the feature and still be left holding an empty shell, because the value was never in the shell. It was in the data, the relationships, and the context the shell was built to carry.

Where the Moat Moves
#

When the feature stops being the moat, the advantage moves to the layers that surround it, and almost all of them are things that compound through time rather than through code. Five of them matter for a developer deciding where to spend next quarter.

The learning loop, not the feature
#

The competitor copies your feature, but they do not copy what you learned by shipping it. Shipping a feature in front of real users tells you which half of it was wrong, which edge case matters, and which adjacent problem is now the real one. That knowledge is yours alone until competitors run the same experiment themselves, and they will now run it by copying your result rather than discovering their own. The moat is the build-measure-learn cycle compressed to days, run against real users, faster than anyone who is copying can run it. A feature is no longer a deliverable; it is a probe, and the team that runs more probes per month learns more about the market than the team that ships fewer, more perfect features.

Proprietary data and feedback
#

A clone of your feature without your data is a weaker feature. The recommendation is bland, the search results are generic, the anomaly detection fires on the wrong things, because the model behind the clone has nothing the field has not already seen. Every interaction with a real user adds signal to your data that the clone cannot synthesize, and this compounds quietly until the gap is not closeable by better code. This compounding is the mechanism behind network effects, and it is one of the few things that genuinely does not clone.

Workflow depth and switching costs
#

A feature you can use in a minute is a feature you can leave in a minute. A feature that is wired into six other systems, that holds three years of configuration, that your team’s runbook depends on, is a feature that survives a cheaper clone because the cost of moving exceeds the cost of staying. These switching costs are a legitimate moat when they are a side effect of genuine usefulness, and they are built by going deep into the customer’s workflow rather than wide across a feature checklist. Shallow integrations clone in a day; deep ones do not, and depth is a function of how much of the customer’s actual job you have absorbed.

Distribution, brand, and trust
#

Engineers historically treated these as someone else’s problem, which was always a mistake and is now an expensive one. The feature that arrives through a channel the user already trusts, from a name they recognize, beats the marginally better clone that arrives cold. Trust is built slowly, through reliability and through presence, and it is one of the slowest things in the product to reproduce. A developer who invests zero attention here has chosen to compete purely on the layer that clones fastest.

Judgment about what to build
#

Judgment is the layer the rest of this blog keeps arriving at, because the bottleneck keeps moving toward it. When everyone can build anything, building things stops being the differentiator, and deciding which thing to build, for whom, and in what form becomes the whole game. That judgment is a personal and team-level moat, it compounds with practice, and it does not clone because the competitor cannot copy the years of being close to the problem that produced it.

The Feature Race Is a Trap
#

The failure mode to avoid is the feature-parity race, and it is the default response if you do not see the shift.

You ship a feature, the competitor copies it, you ship another to pull ahead, they copy that, and the cycle repeats. Both teams are running as fast as they can and neither is building a moat, because every feature is neutralized within a week of landing. You are exhausting yourselves producing advantages that confer no advantage, and the only thing accumulating is technical debt from features nobody had time to integrate properly.

The feature-parity race is the same trap as first-mover advantage misunderstood. Being first was valuable only because first movers got the growing season, the time for data and habit to form before the copiers arrived. When the growing season disappears, being first stops being the point. Being the one who learns fastest from being there is the point.

The deeper error is treating the feature list as the scoreboard. It feels like progress, because the features keep shipping and the release notes keep growing. But a competitor watching your changelog now has your roadmap for free, and a model lets them execute it at your speed. A changelog is no longer a strategic asset; in a clonable world it is a blueprint you hand to your competitors every week.

What to Do Next
#

A few concrete moves follow from treating features as probes and moats as the target.

Audit where your engineering effort actually lands. If the large majority sits on building and polishing features, you are over-invested in the layer that clones and under-invested in the layers that do not. Reallocate deliberately, not by abandoning features, which you still have to ship, but by capping the time each feature gets and routing the surplus into data, integration depth, and the learning loop.

Instrument every feature as an experiment from day one. If you ship a feature and cannot tell within a week whether it moved the metric you built it for, you have shipped a deliverable, not a probe. You have also given up the one advantage the copy does not get. The measurement is the moat, because it is what turns the feature into learning the competitor does not inherit.

Pick a narrow domain and go deep rather than spreading wide. The competitor who clones your broad, shallow surface gets a credible copy. The competitor who tries to clone your deep, specific understanding of one industry’s workflow has to do the years of work you already did, and most will not bother. A moat that survives cloning is built from depth.

Invest in the layers engineers usually skip. Distribution, documentation that lives where users find it, reliability that earns trust, onboarding that makes the product sticky through genuine usefulness rather than lock-in. These compound while features are being copied, and they are the reason the copy arrives to an empty room.

And protect the judgment layer on your own team. The skill of deciding what to build is now the highest-leverage skill a developer can hold, and it is built by staying close to users, not by staying close to the IDE. Delegate the building aggressively so that the time you reclaim lands on the judgment, the data, and the relationships, because those are the three things the clone will never contain.

The Moat Moved
#

The feature stopped being the moat the day it became cheap to copy. That shift is not a threat to the developers who notice, because the moat did not disappear; it moved to a set of layers that reward exactly the attention most engineers have been trained to underinvest in. Data, distribution, workflow depth, trust, and judgment all compound, and none of them clone.

The teams that win this era will still ship features, because they have to. They will just stop treating the features as the point. The feature is the seed; the moat is the growing season, and the growing season is now made of everything except the code.

See also
#

References
#

  • Economic moat - the structural sources of sustained advantage, the canonical list against which a feature is revealed to be a seed rather than a moat
  • Commoditization - what happens when a previously differentiated layer becomes cheap and standard, which is what happened to the application feature layer
  • Switching barriers - the workflow-depth moat that does not clone, built by absorbing more of the customer’s actual job
  • Network effect - the data-and-usage moat that makes a clone strictly weaker than the original it copied
  • Lean startup - the build-measure-learn framing that turns a feature from a deliverable into a probe, the learning loop that outpaces copying
  • First-mover advantage - why being first was only valuable during the growing season, and why that advantage compresses as copy-time collapses

The Acceptance Gap: Why an LLM Solution Is Not a Shipped Solution

Generation is solved. You describe, the model produces, and the candidate looks plausible in seconds. The bottleneck is no longer producing a solution; it is deciding that a solution is acceptable, and that gap is the one the model cannot close on its own.

I keep noticing the gap in two forms, and they fail for different reasons, which is why a single strategy like “review the output” addresses neither one well. One is a bug fix that the model swears it fixed and did not. The other is a feature that meets the description and still is not what I wanted. Both feel like the model failed, but the failure is in a different place each time, and the difference is the whole point.

The Gap Is Not One Gap
#

The distance between “a description of what I want” and “an acceptable solution I would ship” is not a single gap. It is two, stacked, and they respond to completely different interventions.

The first gap is about correctness. Did the change do the thing it was supposed to do, in the world, against ground truth the model cannot see? The second gap is about fit. Does the result match the thing I actually wanted, most of which I never wrote down?

Correctness is, in principle, objective. You can check it. Fit is, in practice, subjective. You can only feel it.

Most of the frustration people report with LLM coding comes from treating these two gaps as the same gap, and applying the tool that closes one to the other. The bug gap wants a check; the feature gap wants a reaction, and reaching for one when you need the other is why the work keeps coming back unfinished.

Bug Fixes: The Silent-Failure Gap
#

When I ask an LLM to fix a bug, it returns a patch that looks correct. It will explain the root cause in a confident voice, write a plausible diff, and tell me the issue is resolved. Often it is. Sometimes the patch addresses a symptom and the root cause resurfaces next week. Sometimes it fixes the exact reproduction I pasted but not the general case. Sometimes it fixes nothing at all, and merely rearranges the code into something that looks like a fix.

The model cannot tell me which of those happened, because the model has no access to the ground truth that would let it verify its own claim. It optimized for “a plausible fix,” not for “a verified fix.” Its confidence is not evidence, and nothing in the tone of the output distinguishes a real fix from a convincing one.

This is the dangerous kind of failure, which testers have always called the oracle problem: without an independent way to decide what the correct output is, you cannot tell that a plausible output is wrong. The model has the problem in its most acute form, because it is both the thing producing the answer and the thing narrating why the answer is right. The narrator is not independent of the guess.

So for bug fixes I end up verifying manually. I reproduce the original failure, apply the patch, and check whether the failure is gone. Not because I enjoy the step, but because the model’s report of “fixed” is a hypothesis, not a result. A fix is not fixed until something independent of the model says so.

Features: The Taste Gap
#

When I ask an LLM to build a feature, the gap is different, and it fails for a different reason.

The feature works, in the narrow sense that it does what the description said. The gap is that “meets the description” is not “matches what I wanted,” because most of what I wanted was never in the description. It lived in taste. The feel of the interaction. The expectation about a default. The sense that this control belongs here and not there, that the empty state should say this and not that, that the feature is finished when it feels light rather than heavy.

I did not write any of that down, because I did not know I wanted it until I saw the result that lacked it. This is the nature of subjective requirements: they are discovered by contact with the artifact, not enumerated in advance. A specification can carry the objective part of what you want; it cannot carry the taste, because the taste is a reaction you have not had yet.

So the loop for features is not “verify,” it is “try.” Generate, run it, notice the distance between what I got and what I expected, describe that distance, regenerate. When the distance closes to zero, I stop. That stopping point, the “just ship it” moment, is a taste judgment, not a verification step. No test defines it. I define it, by being satisfied.

Why the Model Cannot Close Either Gap Alone
#

The two gaps look different, but they share one cause. Both are acceptance gaps, and acceptance requires information the model does not possess.

For bugs, the missing information is the ground truth of correct behavior. That truth lives outside the model, in an executable check or in a human observation. The model can guess at it, but it cannot consult it. For features, the missing information is my taste. That lives outside the model too, in the reaction I will have when I try the result. The model can guess at it from my description, but it cannot feel it.

In both cases the model can generate candidates freely, and in both cases it cannot sign off on them. Signing off requires exactly the external information that was never in the prompt, which is why no amount of rephrasing the prompt closes the gap.

This is the same pattern I described in The Shifting Bottleneck: automating a layer does not remove the layer, it moves the constraint to the layer above it. Here the automated layer is generation, and the layer above it is acceptance. The work did not go away. It turned into deciding whether the generated thing is good enough.

What Closes Each Gap
#

The two gaps respond to different interventions, and the strategy is to match the intervention to the gap.

The bug gap is closeable in principle, and the mechanism is encoding. Write the acceptance criterion as a check the model cannot fake. A failing test that must pass. A reproduction script that must go green. A property the output must satisfy, stated before the fix is written. Once the check exists, the model can run it, and its claim of “fixed” becomes trustworthy only when the check agrees. The bug gap shrinks to exactly the set of bugs for which I have not yet written a check.

This is test-driven development, rediscovered as the answer to “why don’t I trust the model’s fix.” The discipline is to write the check before, or alongside, the fix, not after. A bug fixed without a check is a bug I will have to verify by hand, forever, because nothing is keeping it fixed. A bug fixed with a check stays fixed, because the check will scream if it regresses, whether or not I am looking.

The feature gap is not closeable the same way, and this is the uncomfortable part. I cannot write a test for “this feels right,” because I do not know the specification of my own taste until I see the result. Exploratory testing and specification by example help me surface more of what I want, but they cannot surface all of it, because the residual is a reaction, not a requirement. The feature gap closes only through iteration, and the terminal condition is a human saying “good enough, ship it.”

There is no encoding that removes the human from the feature loop, because the human’s reaction is the signal the loop is measuring. The best I can do is make the loop fast, so that each try is cheap and I can afford many of them. A model that generates in thirty seconds and an environment where I can try the result in ten more is a loop I can run ten times in a morning, and the tenth version is usually the one I ship.

The Mistake Is Treating Them as the Same Gap
#

Most of the waste in LLM-assisted work comes from applying the wrong tool to the wrong gap.

Treat the taste gap as a verification problem, and you write tests that pass and ship features nobody likes. The tests confirm the feature does what the spec said, which was never the question. The question was whether the spec was the right spec, and no test answers that.

Treat the verification gap as a taste problem, and you manually re-check, by hand, things the model could have checked for itself. You read a diff looking for whether the bug is really fixed, applying your eyes as a slow and unreliable oracle, when a failing test would have answered in a second and answered the same way every time. You burn the attention you should have been spending on taste on work the model could have done for you.

The split is sharp once you see it. If the gap is “did it do the thing,” that is a check, and the move is to encode the check so the model runs it without you. If the gap is “is this the thing I wanted,” that is taste, and the move is to iterate fast and trust the stopping judgment. Verification and validation are the old words for this distinction, and they have never been more useful than they are now: verify against the spec, validate against the want. The model can help with the first. It cannot do the second for you.

What to Do Next
#

Sort the next ten things you hand to the model into two piles.

The bug pile gets a check for each item, written first. If you cannot write a check that would fail before the fix and pass after it, you do not yet understand the bug well enough to delegate it, and the model’s fix will be a guess you have to verify by hand anyway. The check is the thing that makes delegation safe.

The feature pile gets a fast iteration loop. Cut anything that slows down the try-it-and-react cycle, because the cost of a feature is no longer the cost of building it, it is the cost of the number of tries it takes to match your taste. A model that builds cheaply makes many tries affordable, and that is the real lever.

Leave the “is this good enough to ship” judgment to yourself. Generation is no longer the bottleneck, and neither, soon, is verification, once you encode it. The bottleneck is acceptance, and the half of acceptance that is taste is the last compounding thing you do. Nobody can write that prompt for you, which is exactly why it is the part worth keeping.

See also
#


github-board - A kanban board for any GitHub search

GitHub’s issue and PR lists are flat. When you’re tracking a dozen repositories, or triaging hundreds of items, a flat list stops being a useful view of your work. GitHub Projects exists, but it demands manual triage and won’t adapt to an ad-hoc layout you want for the next ten minutes.

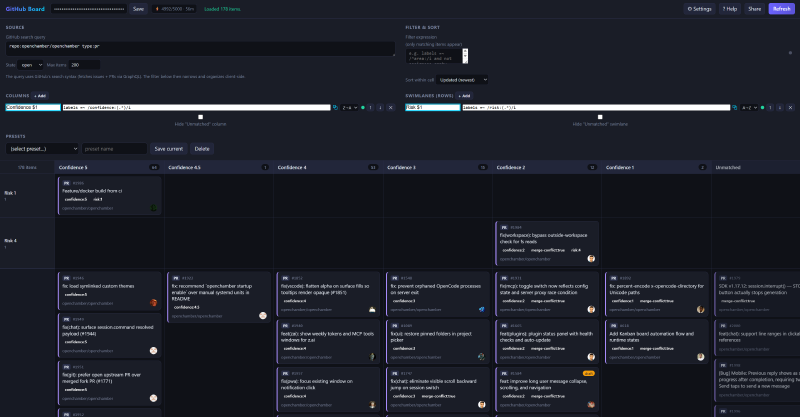
I built github-board to fix this. It turns any GitHub search into a customizable kanban board, defined entirely by small filter expressions. There is no backend, no build step, and no framework. You open index.html in a browser, paste a token, and sketch a board in seconds against live data. Try it live at tomzxcode.github.io/github-board.

github-board overview

The problem
#

A GitHub issue list answers one question well: what is in this repo, in this state. It answers almost every other question poorly. Which of my open PRs are drafts, which are waiting on review, and which have gone stale? How are issues spread across the area:* labels? What does the backlog look like across an entire organization?

You can build a GitHub Project board to answer these questions, but each card has to be placed and maintained by hand. The board reflects triage you did, not the state of your data right now. For a recurring view that’s worth the effort. For a one-off question you want to answer in 30 seconds, it isn’t.

How it works
#

You give github-board a search query, the same syntax the GitHub search bar already understands.

repo:owner/name

Then you define columns with boolean expressions over the fetched items. The board fetches up to 2000 issues and PRs through the GraphQL API with pagination, then groups them into columns entirely in your browser.

A default board ships with Draft PRs, Open PRs, Open Issues, and Closed columns. Each column is just an expression, and the board re-renders live as you type.

Columns and swimlanes as expressions
#

Every column is a filter expression against fields like type, state, labels, assignees, and dates.

type:pr and state:open and draft
type:issue and state:open and label:bug
state:closed and updated > -7d

The expression language supports the operators you’d expect: ==, =~, <, contains, in, exists, empty, plus regex matching and relative date math like -7d, -2w, -1y.

You can add a second dimension with swimlanes (rows), so a board can group issues by assignee across the same set of status columns, all from one query.

Auto-split with a $1 capture
#

Auto-split is the feature I use most. If you put a $1 capture in a column or lane rule, github-board expands it into one bucket per distinct matched value.

Name a lane area:$1 matching labels =~ /area:(.*)/i, and you instantly get one row per area label that exists in your data. Name a column the same way and you get one column per label. No manual setup per bucket, and buckets with no items simply don’t appear or stay empty depending on your preference. The $1 capture is the fastest way to see how work distributes across a category you didn’t know you cared about until just now.

Shareable links and presets #

The entire view (query, filter, columns, swimlanes, and sort) is encoded in the URL hash. Click Share, send the link to a teammate, and they see your exact board using their own token. The token is never included in the link, so you can paste it anywhere.

For boards you return to, save the full configuration as a named preset. Presets persist in localStorage alongside your token, so everything stays in your browser.

Privacy and scope
#

github-board is read-only and has no backend. Requests go directly from your browser to api.github.com. You bring your own personal access token, which is stored only in your browser’s localStorage. There is no OAuth flow, no server logging, and no way for the tool to modify your issues or pull requests.

github-board is a view, not a project-management tool. There is no drag-and-drop across columns, because the source of truth is your data, not where a card was dropped.

Getting started
#

No install is required.

  1. Open tomzxcode.github.io/github-board (or open index.html from the repo).
  2. Paste a GitHub personal access token with read access to what you want to view.
  3. Open Settings and enter a query like repo:owner/name or org:your-org.
  4. Click Refresh and adjust the columns to match your workflow.

If you already use gh-cached to browse issues without burning your rate limit, or ghx for agentic code reviews, github-board is the visual counterpart: the same GitHub data, arranged the way you want to see it right now.

See also
#

  • gh-cached - browse GitHub issues and PRs from a local cache to avoid rate limits
  • ghx - a CLI for the inline comment and review operations the gh CLI doesn’t expose
  • Triaging open source pull requests - the kind of high-volume review work github-board is built to visualize
  • Backlog management best practices - principles for keeping a backlog scannable that expression-driven boards make concrete

llm-augmented-workflows - A config-driven automation engine for GitHub, powered by opencode

GitHub ships a perfectly good event bus. Issues get opened, labeled, and closed; PRs get reviewed and merged; comments land on lines and threads. Every one of those events is a chance for an LLM agent to do useful work, triage the issue, draft a plan, reproduce a bug, post a review. The gap is not the events and it is not the agents. The gap is the glue between them.

Today that glue is per-flow YAML. Every workflow you want to automate gets its own triage.yml, plan.yml, implement.yml, each with its own copy of the agent invocation boilerplate, its own trigger, its own label math, and its own drift. Add a fourth flow and you copy the file again. Change how the agent is called and you edit all of them. The workflows describe the same agent doing different things, but they share nothing.

I built llm-augmented-workflows to collapse all of that into one file. You describe every flow as event-matched rules in a single .github/llmaw/flows.yml, and the dispatcher routes GitHub events to the right agent skill, with token-free label and shell steps for the transitions that do not need a model.

The problem
#

The moment you try to automate more than one agent-driven flow, the per-file pattern buckles.

Each flow duplicates three things it should not. First, the wiring: trigger on this label, run the agent, relabel, wait for the next event. Second, the agent invocation: which model, which skills repo, which timeout, which working directory. Third, the outcome handling: what to do when the agent says approved, rejected, or needs changes.

That duplication is not free. Workflows drift from each other. The agent invocation that worked yesterday is copy-pasted into the new flow with the old model id. A label rename in one file does not propagate to the others. And the parts of the flow that do not even need an LLM, relabeling an issue, posting a canned comment, closing a linked issue on merge, still pay for a model call because that is what the file is built around.

What you want is to describe the flow once, and let the engine handle the wiring.

How it works
#

The engine is a small stateless dispatcher with one reusable GitHub Actions workflow. State lives entirely in GitHub, in labels, issues, and PRs. The engine reads an event, matches it against flows.yml, runs the matched rule’s pipeline, and exits.

GitHub event (issue labeled, PR merged, comment, ...)
   |
   v
dispatch.yml  reads flows.yml  ->  route matches rule(s)
   |
   v
for each matched rule, run-rule runs its whole `run` in one pass:
   labels/shell (pre) -> skill (opencode) -> labels/shell (post) -> on_outcome
   |
   v
the agent acts on GitHub (relabel, comment, open PR, close) -> emits new events

The pipeline is the unit of work. A rule’s run is an ordered list of steps, and the engine runs them in one pass: token-free label and shell steps can run before and after the agent, the agent step calls an opencode skill, and on_outcome maps the agent’s verdict to labels, a close, or a comment. Because relabeling emits a new event, the next phase of the flow is just another rule that matches the new label. Terminal outcomes fall out naturally: an agent closes an issue (won’t fix), or a PR merges and an on-merge rule closes the linked issue.

One config file, not one workflow per flow
#

Every flow lives in .github/llmaw/flows.yml. A flow is a list of rules, and a rule is a when (the event match) plus a run (the ordered pipeline).

defaults:
  model: opencode/deepseek-v4-flash-free
  agents_repository: tomzx/agents
  timeout_minutes: 30
flows:
  plan:
    rules:
      - id: generate-plan
        when: { event: issues, action: labeled, label: plan-needed }
        run: [ { skill: generate-plan } ]
      - id: on-plan-merged
        when: { event: pull_request, action: closed, merged: true, branch_prefix: plan/ }
        run: [ { labels: { add: [plan-approved], target: linked-issue } } ]
      - id: implement
        when: { event: issues, action: labeled, label: plan-approved }
        run: [ { skill: implement-plan } ]

Read it top to bottom and that is the whole flow. An issue gets plan-needed, the generate-plan skill runs and opens a plan/... PR. When that PR merges, on-plan-merged adds plan-approved to the linked issue, no model involved. When the issue is labeled plan-approved, the implement-plan skill runs and implements it. Three rules, one file, one copy of the wiring.

Token-free transitions
#

Token-free transitions are the feature that pays for the whole design.

Relabeling an issue does not require an LLM, and neither does closing a linked issue on merge or posting a deterministic comment. In llm-augmented-workflows, labels and shell steps run without calling the model at all. The on-plan-merged rule above is a single label step: when the plan PR merges, add plan-approved to the linked issue. Zero tokens, zero model latency, just a GitHub API call.

That means the agent only runs where the agent is actually needed, and the transitions between phases are free, fast, and deterministic. A flow that used to cost three model calls (triage, plan, implement) plus the glue between them now costs two, because the glue is a label.

Two execution modes
#

Each matched rule’s pipeline runs in one job. What happens after the pipeline is controlled by the execution mode:

  • event-driven (default): the rule runs once and the job ends. The relabel emits a new event that re-triggers the dispatcher for the next phase. One job per phase, each one independently observable in the Actions log.
  • continuous: the same job keeps advancing to the next rule based on the labels each rule adds, until llmaw:needs-human appears or the chain reaches a resting state. One job per pipeline, the whole end-to-end run in one log.

Set it under defaults.execution or per flow, force it per dispatch via the execution input or the LLMAW_EXECUTION repo variable. Event-driven is easier to debug; continuous is easier to watch flow end to end. The same flows.yml works in either mode, because the mode is about how the engine chains rules, not how the rules are defined.

Skills come from your agents repository
#

The skill step does not run an inline prompt. It runs an opencode skill sourced from a configurable agents repository, tomzx/agents by default, overridable with AGENTS_REPOSITORY.

That separation matters. The flow definition says what should happen and when. The skill definition says how the agent should do it. When you improve the generate-plan skill, every flow that references it gets the improvement, without touching flows.yml. When you add a new flow, you reference an existing skill instead of inlining a prompt that will drift.

The default flow runs on the free model
#

The default model is opencode/deepseek-v4-flash-free, and it needs only the auto-provided GITHUB_TOKEN. You can adopt the engine on a throwaway repo without provisioning a single secret. Override per repo or per org with OPENCODE_MODEL, point AGENTS_REPOSITORY at your own skills, raise LLMAW_MAX_ITERATIONS for long continuous runs, and you are done.

Getting started
#

Three steps.

  1. Add one wrapper workflow to your repo, pinning the dispatcher by ref.

    .github/workflows/llm-workflows.yml

    name: LLM Workflows
    on:
      issues: { types: [opened, labeled, reopened, closed] }
      pull_request: { types: [closed, labeled, ready_for_review] }
      issue_comment: { types: [created] }
      pull_request_review_comment: { types: [created] }
    permissions:
      contents: write
      pull-requests: write
      issues: write
    jobs:
      dispatch:
        uses: TomzxCode/llm-augmented-workflows/.github/workflows/dispatch.yml@v1
        secrets: inherit
  2. Add .github/llmaw/flows.yml describing your flows. Start from the example above or the docs/flows.md recipes for triage, close-on-merge, and per-step overrides.

  3. Run the Setup Labels workflow to create the labels declared under labels:, or let your flows add them as needed.

Pin @v1 for the latest within a major tag, @main if you want to track the tip, or @<full-sha> for an immutable production pin.

Consumers never copy the engine. The dispatcher checks this repository out into .llmaw/ on the worker and runs uv run --project .llmaw llmaw ..., pinning the version via the wrapper’s uses: ref.

What it does not do yet
#

The engine’s unit of work is one issue per workflow execution. A matched rule runs, the agent acts, the job ends (or chains within continuous mode until needs-human), and the next event is the next run. That model maps cleanly onto small, well-scoped work: triage this issue, plan this feature, reproduce this bug, implement this task.

It does not map onto a large epic. A change that spans many tasks, many PRs, and many days cannot be implemented by a single issue’s pipeline, because the engine has no concept of an epic as a first-class object that owns child issues and tracks their aggregate progress. To implement a large change today, you have to break the epic into per-task issues yourself, outside the engine, and let each of those issues run its own one-issue pipeline. The decomposition step, deciding how to split the work and how the pieces depend on each other, is not automated.

Closing that gap is the next phase of the problem, and it is where the needs-human checkpoint currently has to do the most work. Until the engine can take an epic, decompose it into ordered tasks, and drive each task through its own run while tracking the whole, large changes stay a manual decomposition followed by automated execution.

Why this structure
#

I have been writing about the pieces of this for a while. Loops as Files argued that the trigger layer deserves the same treatment as the prompt layer, versioned, reviewable, owned next to the behavior it schedules. The Self-Evolving Repository pushed the question of how far you can take a GitHub project where every maintainer function is replaced by an automated loop. llm-augmented-workflows is the engine for both: the flows file is the schedule, the skills are the behavior, and the state never leaves GitHub.

If you already use ghx for agentic code reviews or github-board to visualize your issues, llm-augmented-workflows is the layer that makes the issues move on their own.

See also
#

  • Loops as Files - the scheduling layer that flows.yml makes concrete per repository
  • The Self-Evolving Repository - the end state this engine is built toward
  • ghx - the CLI the review skills use for inline PR comments the gh CLI does not expose
  • github-board - a kanban view over the same GitHub state these flows mutate
  • The Merge Gate - why the human checkpoint (llmaw:needs-human) stays in the loop

Defects Flow Downstream, Fixes Must Flow Upstream

The further upstream a defect is born, the more code it contaminates, and the more expensive it becomes to remove. This has been true for as long as software has had a lifecycle. Two things have changed, and both point the same way. First, the generation step is now automated, so upstream defects are materialized downstream at machine speed. Second, the old habit of patching defects in place no longer buys what it used to. Once the pipeline executes itself, the only durable fix is the one made at the source, and every fix made downstream is a patch you will have to make again.

The Pipeline Has Always Run One Way
#

Software development is a cascade. Each stage constrains the next: needs become requirements, requirements become a specification, the specification becomes an architecture, the architecture becomes code, the code is verified, shipped, and operated. A decision at any stage narrows the space of what is possible at every stage below it, and an error at any stage is inherited by everything that descends from it.

This directionality is why the cost of removing a defect rises so steeply the later you find it. Boehm and Basili put a number on it more than two decades ago: finding and fixing a software problem after delivery is often a hundred times more expensive than finding and fixing it during requirements and design. The exact multiplier is debatable, but the slope of the curve is not. Each stage a defect survives multiplies its removal cost, because each stage builds artifacts on top of it that all have to be reworked when the foundation moves.

The industry already has a name for the obvious response. It is called shift-left testing, and the move it prescribes, pushing verification earlier in the lifecycle, is correct as far as it goes. But shift-left is a half-measure, because it moves the act of checking earlier without moving the act of fixing to where the defect was born. The deeper move is not “test earlier.” It is “fix at the origin,” and the two are not the same. Testing earlier finds the symptom sooner; fixing at the origin ensures the symptom is never generated again.

The Amplifier Got an Engine
#

Before LLMs, a human wrote the code, and the human was a lossy interpreter of the specification. That lossiness was quietly essential. When the spec was ambiguous, the human made a judgment call, often a reasonable one, and that judgment absorbed some of the upstream defect before it could reach the running system. The defect still propagated, but through a mind that could correct it on the way down.

The model does not absorb ambiguity. It resolves it, once, in the direction of whatever is most probable, and then it materializes that resolution across every file it touches. The generation step stopped being a filter and became an amplifier, and it amplifies whatever it was given, including the gaps. One ambiguous line in a specification becomes a dozen consistent, plausible, uniformly wrong code paths, in seconds, and they all look correct because they all agree with each other.

This is the real intensification. The cost curve was always steep, and it is now steep and fast. The window in which a human used to catch an upstream defect by “just writing the code” has closed, because the code writes itself before the human has time to notice the spec was vague. By the time anyone reads the output, the upstream defect has already been faithfully reproduced across the diff, and the reviewer is left arguing with the symptom instead of the cause.

Why Consequences Fan Out
#

The reason early stages outrank late stages is not only that they are cheaper to fix. It is that their defects multiply downstream while late-stage defects mostly do not.

A bug in code affects the code that contains it. A gap in the architecture affects every component built on top of it. A missing or wrong requirement affects every architecture that tries to satisfy it, every component that implements it, every test that verifies it. The earlier the stage, the larger the fan-out, because the larger the subtree of artifacts that descend from it.

This fan-out is why a specification defect is not just “a bug, but earlier.” It is a different category of problem, one whose blast radius grows with the distance from the source. A single ambiguity in a spec can be the common ancestor of a hundred production incidents, each of which looks like a separate bug to the engineer who responds to it, and each of which is, in fact, the same bug wearing different clothes. Treat them as separate bugs and you will fix a hundred symptoms. Treat them as one and you fix the spec once.

Nancy Leveson reached the same conclusion from the study of accidents in Engineering a Safer World. Serious failures are rarely caused by a single component breaking. They are caused by flawed control structures upstream that set the components up to fail in concert, and the component failure is merely the place the upstream flaw became visible. The component is the symptom. The control structure is the cause. Fixing the component prevents that one incident, and fixing the control structure prevents the class. A pipeline stage is a control structure, and in software the earliest stages are the ones with the widest reach.

The Fix Belongs Upstream
#

Here is the operational consequence, and it is the whole argument in a single rule.

When a defect appears in code, there are two places to fix it. You can fix the code, which removes the symptom from this instance. Or you can fix the upstream artifact that produced the code, which removes the cause from every instance.

These look similar and are not. A code fix is a non-compounding fix. It patches one occurrence, leaves the source intact, and guarantees that the same defect will be regenerated the next time the pipeline runs against the same upstream artifact. A spec fix is a compounding fix. It changes the source, and every future generation inherits the correction automatically, for as long as the artifact exists.

This is the same compounding-versus-one-time distinction that makes specification outrank review, as Rethinking Code Review in the Age of LLMs argues: review catches a defect once, for the reviewer who happens to be reading, while a spec prevents the whole class from being generated. The principle does not stop at review. It runs the entire length of the pipeline. The defect you patch in code today is the defect the model writes again tomorrow from the same ambiguous spec, and the defect you fix in the spec today is the defect the model never writes again.

The discipline this implies is uncomfortable for teams that grew up triaging bugs at the bottom of the pipeline. It says that most “code bugs” in an AI-assisted codebase are not code bugs at all. They are specification bugs, or architecture bugs, that happened to surface in code. Treating them as code bugs, by fixing the code, is treating the symptom while leaving the disease in place to generate fresh symptoms next sprint.

A useful diagnostic comes straight from the five whys and the Toyota andon tradition: when the same class of bug appears more than once, stop the line, walk back up the pipeline asking why until you reach a process cause, and fix the process, not the product. Fixing the product gets you a working unit today. Fixing the process gets you a working line forever. The two investments have almost nothing in common, and teams that confuse them spend their lives re-fixing the same bug in new files.

What This Changes About Where You Spend Effort
#

If consequences amplify downstream and fixes compound upstream, then the allocation of engineering effort across the lifecycle is exactly inverted from where most teams spend it.

Most effort sits at the bottom of the pipeline. Writing code, reviewing code, fixing code, fighting fires in production: these are the stages with the smallest blast radius and the least compounding return. They feel urgent because they are where the pain is visible, but they are also where an hour of effort buys the least durable improvement, because the upstream artifacts that produced the pain are still in place, still generating.

The high-leverage stages are at the top. Requirements, specification, and architecture are the stages whose defects fan out the widest and whose fixes compound the longest. They feel less urgent because the pain they cause has not happened yet, and when it does happen it will be blamed on the code, not on the spec that produced the code. The trap is that the bottom of the pipeline is loud and the top of the pipeline is quiet, and most teams optimize for the noise rather than for the leverage.

This is the same relocation The Shifting Bottleneck describes from a different angle. Once code writes itself, the bottleneck moves to verification, and the highest-leverage response is not to verify harder but to specify better, because specifying better reduces the volume of bad output that verification ever has to catch. The pipeline does not reward you for being good at a late stage. It rewards you for making the late stage unnecessary by being good at an earlier one.

What to Do Next
#

A few concrete moves follow, and each is an inversion of the default.

Treat every repeated bug class as an upstream defect. When the same kind of issue shows up a second or third time, stop fixing it in code. Walk back up the pipeline until you find the artifact that allowed it, and fix that. The rule is blunt and useful: fix at the source once, or fix at the symptom forever.

Invest disproportionately in specification. The spec is now the highest-leverage artifact in the pipeline, because it is the stage whose defects fan out the widest and whose fixes compound the longest. A team that under-invests here pays for it in every downstream stage, forever, at machine speed, and a team that over-invests here barely notices the downstream stages at all.

When you review, review the spec, not the code. Code review catches symptoms once, on the diff that happens to be in front of the reviewer. Spec review prevents classes of symptoms from being generated at all, across every future diff. An hour on the spec outranks an hour on the code, because the code is downstream of the spec and the spec constrains every diff that will ever be written from it.

Keep an upstream ledger on incidents. When something breaks in production, record not just the code-level cause but the pipeline stage where the defect was actually born. Over a quarter the pattern will show which upstream stages are leaking the most, and that is where investment pays back the most, because a single fix there retires a whole family of incidents.

And when the model produces bad output in the same module twice, do not write a longer prompt. Fix the module, or fix the spec that describes it, because as The Importance of Context When Interacting with LLMs argues, the upstream artifacts are the model’s context, and bad output is the truest signal you will ever get about where that context is incoherent. The model is showing you the leak. The right response is to fix the pipe, not to mop the floor faster.

The Lifecycle Runs One Way
#

Defects ride the pipeline downstream and multiply as they go. Fixes can ride it upstream, and they multiply too, but in the opposite direction: one fix at the source prevents a thousand fixes at the symptom.

The team that understands this spends its best hours at the top of the pipeline, writing specifications and architectures that make most downstream defects impossible. The team that does not spends its best hours at the bottom, fixing code that the pipeline keeps regenerating from sources it never touches. Both teams are busy. Only one of them is getting durable work done. In an era when the downstream stages execute themselves, the only engineering that compounds is the engineering done at the top of the pipeline. Everything below it is maintenance.

See also
#

References
#


Read the Commits, Not the Manual: What OpenClaw's Git History Reveals About Scaling a Project

The most revealing document a software project writes is not its README, its CONTRIBUTING.md, or its architecture diagram. It is its commit history, because the commit history is the one artifact the project cannot rewrite after the fact. A process doc describes the project the maintainers wish they were running, and the commit log describes the project they are actually running, and the gap between the two is where every real lesson lives.

I spent time inside the git history of OpenClaw, a self-hosted personal AI assistant that talks to you across roughly two dozen messaging channels. It is an extreme case, and extreme cases are the easiest to read. In about seven months it accumulated over sixty-two thousand commits from more than three thousand contributors, which is somewhere close to two hundred and ninety commits a day, every day, since its first commit. That is a throughput at which most projects would have collapsed into an unreadable knot, and it did not. The interesting question is why, and the commit history answers it more clearly than any roadmap could.

This article is a reading of that history, and the throughline is a single observation that the data makes impossible to miss. A project’s real architecture is not the dependency graph of its packages. It is the role structure of the people who land commits on it, and OpenClaw reveals that role structure with unusual clarity because it is large enough that the patterns survive any individual’s bad week.

The First Thing the Commits Show: Two Kinds of Maintainer
#

Run a contributor breakdown on any mature project and you will find that the top commit counts are dominated by one or two names. OpenClaw is no different. The founding maintainer, Peter Steinberger, is listed in CONTRIBUTING.md as “Benevolent Dictator,” and he accounts for well over half of all commits in the repository, roughly three times the next contributor. The second name down is Vincent Koc, listed as owning “Agents, Telemetry, Hooks, Security.”

You can read their titles and learn nothing, or you can read their commits and learn everything. The commit prefix and the merge behavior are the two signals that tell you what a maintainer actually does all day, and at OpenClaw they tell two completely different stories.

Roughly ninety-five percent of Peter Steinberger’s recent commits land straight on main with no pull request at all. His work spans every conventional-commit prefix in roughly equal measure: test:, fix:, docs:, ci:, refactor:, perf:. His scopes are the product itself, the agents, the gateway, the release machinery, the high-traffic channels. Read his last two hundred commits and you are watching someone build outward, exploring whatever he finds interesting that week, shipping releases, writing the docs for features he just invented, and rarely pausing to open a pull request against his own work.

Vincent Koc’s history is the mirror image. His recent work is almost sixty percent fix commits, and his scopes are a completely different surface: end-to-end tests, the QA lab, scripts, CI, and a scope that appears nowhere near the top of Peter’s list, deadcode. He opens pull requests. He uses the review process. Where Peter’s commits read as exploration, Vincent’s read as consolidation.

The contrast between Peter’s history and Vincent’s is the observation that triggered this article, and the temptation is to read it as a process failure on Peter’s part, the founder cutting corners, ignoring the queue, doing whatever he wants. That reading is wrong, and it misses the point. The two patterns are not the same job done at different levels of discipline. They are two different jobs, and a project of this size needs both of them to survive.

The Benevolent Dictator and the Steward
#

Strip the moral framing away and what you are looking at is a role separation so fundamental that every healthy long-lived project eventually rediscovers it, whether it documents the split or not.

One role is the visionary, the person whose job is to push the frontier outward. They build features that no user has asked for yet, because no user knows to ask for them. They write docs in the same commit as the code, because to them the doc is part of the feature. They commit straight to main because the bottleneck they are optimizing for is their own momentum, and stopping to open a pull request against themselves would be pure ceremony. The visionary does not read the issue tracker for direction. They read it, when they read it at all, for confirmation that the thing they already wanted to build has some demand. Their commits are the product roadmap, written in real time.

The other role is the steward, the person whose job is to keep the frontier from collapsing behind the visionary. They fix the bugs the new features introduced. They write the end-to-end tests that prove the feature actually works under load. They remove the dead code the visionary left behind when they pivoted. They route pull requests from the long tail of contributors through review, because someone has to, and the visionary will not. Their commits are almost entirely fix, test, refactor, chore, and they open pull requests not out of greater virtue but because their work touches shared, critical surface where a mistake costs everyone.

The visionary produces the entropy that makes the project grow, and the steward does the work that keeps the entropy from being fatal, and neither role is superior to the other. A project with only visionaries ships exciting broken things that no one can depend on. A project with only stewards stays clean and slowly dies, because no one is building the thing anyone wants to use next. OpenClaw has both, in volume, and that is the first and most important reason it has not collapsed under its own commit rate.

The practical lesson, if you run a project, is to name this split out loud instead of letting it generate resentment in silence. The most common failure mode is a steward who slowly concludes that the visionary is careless, and a visionary who slowly concludes that the steward is a brake on progress, when in fact each is doing exactly the job the other cannot. Peter’s direct-to-main habit is not a defect Vincent is tolerating. It is the signature of a role, and recognizing it as a role is what stops it from becoming a feud.

The Specialist Roles That Only Appear at Scale
#

Past the two primary roles, the commit history surfaces two more contributors whose work is so specialized it would be invisible in a smaller project, and whose existence is itself a signal of size. A project small enough for everyone to do a bit of everything has no specialists, and the appearance of specialists is the commit-history fingerprint of a project that has grown past the point where generalists can cover the surface.

The third most prolific contributor, going by Shakker, has roughly four thousand commits, and about two thirds of them are test:. There is almost no feature work in the history. This is a person whose entire contribution is the safety net, the test fixtures, the regression coverage that lets everyone else move fast without the product silently breaking. A visionary cannot do this work, because it requires the patience to write the hundredth test for a path the fortieth test already almost covered, and a steward is usually too busy putting out active fires to write tests in advance. The test author is a third role, and it is the role that converts the steward’s fixes from one-off patches into guarantees that do not have to be re-earned.

Further down the list, Tak Hoffman has a thousand-plus commits, and he owns a scope that appears in almost nobody else’s history: (regression). Of the hundred-plus commits in the repository tagged fix(regression):, almost all of them are his. Tak is a regression hunter, someone whose beat is not bugs in general but bugs in things that used to work, the specific class of defect that erodes user trust faster than any missing feature can build it. Regression hunting is a discipline of its own, because it requires holding a mental model of how the system used to behave and noticing when a change has quietly violated it, and it is the kind of work that only gets staffed deliberately once a project is large enough that the founding maintainer can no longer hold the whole behavior graph in their head.

The lesson is that the visionary-and-steward split is a starting frame, not a complete one. As a project grows, the roles keep subdividing, and each subdivision is a person whose commits tell you, by their narrowness, exactly what the project is now too large to handle with generalists. Read the contributors with unusual scope concentrations and you read the project’s growing pains written out in advance.

The Second Thing the Commits Show: The Real Architecture Is the Ownership Table
#

Three thousand contributors is a number at which coordination by conversation breaks down completely. You cannot have a meeting with three thousand people. You cannot maintain a shared mental model with three thousand people. The only way a project absorbs that many contributors without descending into a pull-request traffic jam is to partition the work so thoroughly that most contributors never need to talk to each other at all.

OpenClaw does this with an explicit ownership table, and it is the most underrated document in the repository. CONTRIBUTING.md lists roughly thirty maintainers, each with a named specialty: one owns Telegram, one owns the iOS app, one owns Memory, one owns the Discord subsystem, one owns Chinese channels and nothing else. The instruction to contributors is blunt: “Do not guess who to tag,” route through the ownership list, the label automation, and CODEOWNERS instead.

When the surface area of a project exceeds what any one person can hold in their head, the only scalable architecture is a partition, and the partition has to live in a file, not in tribal knowledge. The plugin layout reinforces this from the code side. There are around a hundred and forty-five extensions and only twenty-one core packages, and the project’s own vision document states the principle outright: core stays lean, capabilities ship as plugins, and the bar for adding an optional capability to core is “intentionally high.”

The plugin partition is the same insight as the role split, applied at the level of the codebase rather than the people. You cannot hold one hundred and forty-five channel adapters in your head, but you do not have to, because each one is owned by one person who only has to hold one in theirs. The partition is the architecture, and the ownership table is the partition made durable. A project that grows past a few active contributors without writing this table down is a project that will discover, painfully, that the absence of an ownership map is itself an architecture, an architecture in which the loudest reviewer owns everything by default.

The Third Thing the Commits Show: Every Rule Is a Scar on Reviewer Time
#

The contribution rules in OpenClaw are unusually specific, and a first-time reader will find some of them almost hostile. There is a hard cap of twenty open pull requests per author, enforced automatically, past which your pull requests are labeled and closed. Refactor-only pull requests are refused outright. Test-only or CI-only pull requests that chase a known main failure are refused outright. Pull requests over roughly five thousand changed lines are reviewed “only in exceptional circumstances.” One pull request must equal one issue or topic.

Taken in isolation, the rules read as pettiness. Read as a group they are the scars of a specific, recurring wound, and the wound is always the same. Every one of these rules is a response to something that once drained reviewer attention without producing proportional value, because reviewer attention is the single scarcest, least-elastic resource a project at this scale has.

The visionary can always produce more commits. The contributor pool can always produce more pull requests. Neither of those can produce more maintainer-hours for review, and so the entire rule set is engineered to protect that one bottleneck. The twenty-pull-request cap exists because batch-opened pull requests impose review cost in proportion to their number, not their value. The ban on refactor-only work exists because a refactor that changes no behavior consumes review to confirm it changes no behavior, which is review spent proving a negative. The line limit exists because a five-thousand-line diff cannot actually be reviewed by a human, it can only be rubber-stamped, and rubber-stamping is the failure mode the gate is supposed to prevent.

The rule set is the theory of constraints applied to a volunteer workforce. When you cannot add capacity at the bottleneck, the only lever left is to choke the demand arriving at it, and you choke demand by making rules that reject the classes of work that waste the bottleneck’s time. A rule that reads as harsh to a contributor is almost always a rule that reads as triage to a maintainer who has been doing the job long enough to know which inputs are waste.

The Fourth Thing the Commits Show: They Dogfood the Future of Development
#

OpenClaw builds an AI agent, and it builds it with AI agents, and the commit history makes the second fact as visible as the first.

Bot accounts appear throughout the contributor list. The contribution guide treats AI-authored pull requests as first-class citizens, requiring only that they be marked, with a checklist that asks for the model, the prompt or session log, and a human confirmation that the code is understood. Codex review is not an experiment: it is described as the “current highest standard of AI review,” expected to run on every pull request and to be addressed by the author before a human reviewer is ever bothered.

The reason the dogfooding matters is not that it is futuristic. The project is a live, working answer to the question every team is now fumbling with, which is how to integrate generated code without being flooded by it. The OpenClaw answer is not to ban generated contributions and not to blindly trust them, but to treat their provenance as a required signal and to route that signal into both the review and the reviewer.

OpenClaw’s approach is the provenance argument I made, from the maintainer’s side, in Triaging Open Source Pull Requests: the one piece of information a reviewer most needs about a modern pull request is which model produced it and what prompt produced it, because that is the information that tells you which blind spots to check for. OpenClaw asks for exactly this information, up front, in the template, and it pairs the request with an automated review pass that can be calibrated against the disclosed model. That pairing, disclosure plus targeted automated review, is the most credible workflow I have seen for accepting generated code at volume, and it is sitting right there in a CONTRIBUTING.md that most projects have not yet caught up to.

How to Read a Project This Way Yourself
#

The method that produced these observations is generalizable, and it costs you nothing but a terminal. You do not need access to a project’s Slack, its planning board, or its maintainers’ intentions. You need its git history and three commands.

Start with the contributor breakdown, git shortlog -sne, and look at the ratio between the top name and everyone else. A project whose top contributor dwarfs the rest is a project whose direction is set by one person, and everything else is execution. A project whose top contributors are close in volume is a project run by committee, and its commits will read as negotiation rather than vision.

Then take the top two or three names and compare their conventional-commit prefixes, git log --author=... --format=%s, grouped by prefix. The ratio of fix to feat, the presence or absence of docs and test, the dominance of refactor or chore, these tell you who builds and who maintains, and they tell you in five minutes what would take a month of standups to learn. A maintainer whose commits are sixty percent fix is a steward. A maintainer whose commits span every prefix evenly is a visionary. The prefix distribution is a fingerprint of a role, and reading it is faster and more reliable than reading anyone’s job title.

Finally, count how many of each top contributor’s commits reference a pull request versus landing straight on main. This is the governance signal. A project where even the founder routes through pull requests is a project run by process. A project where one person lands on main freely and the rest use pull requests is a project that has, whether it admits it or not, a benevolent dictator and a steward, and the rest of the contribution rules will make sense once you see the split.

Run this analysis on your own project before you run it on anyone else’s. You may find that the role structure you assume you are running is not the one your commits describe, and the gap is the first thing worth fixing.

What to Do Next
#

If you maintain a project, take an hour and read your own commit history the way this article reads OpenClaw’s. Find your visionary and your steward, and if you do not have both, that is the single most important hiring or delegation decision in front of you. A project with no steward is slowly dying behind a pile of unmerged fixes and unread pull requests, and no amount of feature velocity will save it.

Write down your ownership table, explicitly, in a file, even if it is just three names today. The day you have thirty contributors is too late to invent the partition, because by then the loudest reviewer will have quietly become the owner of everything, and unwinding that is a political problem rather than a documentation one. The partition is cheap to write early and expensive to write late.

Audit your contribution rules as a set, not individually. Every rule that reads as harsh to a contributor should correspond to a specific class of work that once wasted your review time. Any rule you cannot trace back to such a wound is a rule that is probably driving contributors away without earning its cost, and it is a candidate for deletion.

See also
#

  • The Codebase Gardener - the team-codebase argument that standards must be encoded where work passes through them, which is the lens this article uses to read OpenClaw’s rules as reviewer-time conservation
  • Triaging Open Source Pull Requests - the provenance argument this article extends: when the reviewer knows which model wrote a pull request, they know which blind spots to check, and OpenClaw’s disclosure template is a working implementation of it
  • The Merge Gate - the case for gating on the blast radius of a change rather than the existence of a pull request, which is the principle behind OpenClaw’s line limits and its refusal of refactor-only work
  • Rethinking Code Review in the Age of LLMs - why a machine-checked constraint outperforms a tired human scan, the premise behind treating Codex review as the default standard
  • Software Engineering Teams in the Age of AI - which friction is structural and which is waste, the distinction that explains why OpenClaw’s harsh rules are the former and not the latter

References
#

  • OpenClaw on GitHub - the repository whose commit history, CONTRIBUTING.md, and VISION.md are the primary sources for every observation in this article
  • Wikipedia, “Theory of Constraints” - Goldratt’s framing for why you protect the bottleneck rather than adding effort elsewhere, the basis for reading OpenClaw’s rules as reviewer-time conservation
  • Wikipedia, “Benevolent dictator for life” - the canonical name for the role OpenClaw’s commit history reveals in its top contributor, independent of any title